Showing posts with label information retrieval. Show all posts

Wednesday, September 2, 2009

35th Euromicro Conference on Software Engineering and Advanced Applications


On last week, between 27-29 August, it was run the 12th Euromicro Conference on Digital System Design (DSD) and the 35th Euromicro Conference on Software Engineering and Advanced Applications (SEAA) 2009.

Both conferences took place at the Cultural and Conference Center, in the University of Patras. The event put togther research from various places of the world. All of them interested in discussing new ideas, such work in progress, and concluded work. The RiSE group was represented by Yguaratã Cerqueira Cavalcanti, in the SEAA 2009 sessions, where he presented three works from the group, as follows:

1 - Martins, A. C; Garcia, V. C.; Almeida, E. S.; Meira, S. R. L. Suggesting Software Components for Reuse in Search Engines Using Discovered Knowledge Techniques, 35th IEEE EUROMICRO Conference on Software Engineering and Advanced Applications (SEAA), Service and Component Based Software Engineering (SCBSE) Track, Patras, Greece, 2009.

2 - Neiva, D. F. S; Almeida, E. S.; Meira, S. R. L. An Experimental Study on Requirements Engineering for Software Product Lines, 35th IEEE EUROMICRO Conference on Software Engineering and Advanced Applications (SEAA), Service and Component Based Software Engineering (SCBSE) Track, Short Paper, Patras, Greece, 2009.

3 - Silva, F. R. C; Almeida, E. S.; Meira, S. R. L. A Component Testing Approach Supported by a CASE Tool, 35th IEEE EUROMICRO Conference on Software Engineering and Advanced Applications (SEAA), Service and Component Based Software Engineering (SCBSE) Track, Short Paper, Patras, Greece, 2009.

The paper "A Component Testing Approach Supported by a CASE Tool" was presented in the SCBSE: Component-based Systems Correctness and Test session. In conjunction with this work, several other articles were presented , showing really interesting approaches.

The paper "Suggesting Software Components for Reuse in Search Engines Using Discovered Knowledge Techniques" was presented in the session SCBSE: Experiences and Applications. And th paper "An Experimental Study on Requirements Engineering for Software Product Lines" was showed in the session SPPI: Empirical Approaches.

All the work presented were very interesting. People showed a lot of new ideas to solve the most well know problems regarding SCBSE, and the importance of the empirical approaches session should be emphasized, since there is a lack of well made empirical validation in most of CS work.

Oh, we had also a very amazing gala dinner organized by the Euromicro committee, in front of a very beautiful beach. There we could taste really nice Greek food, and it was also possible to see some Greek dance and to listen Greek music. Really nice!!!

The next Euromicro will take place on Lilly, France. I hope to see you there.

Saturday, May 3, 2008

Applying a Semantic Layer in a Source Code Retrieval Tool


Today, a master thesis of a RiSE member is published in this blog.

Here is the abstract of the work: The challenge for achieving a more efficient software engineering practice comprises a vast number of obstacles related to the intrinsic complexity of software systems and their surrounding contexts. Consequently, software systems tend to fail in meeting the real needs they were developed to address, consuming more resources, thus having a higher cost, and taking longer to complete than anticipated. The software reuse field is often regarded as the most promising discipline for closing these gaps, however, models and tools are still immature to make its adoption on a systematic fashion.

To promote the development of practices, models and tools are welcome activities to boost the reuse activity in most software development organizations. The lack of knowledge about reusable assets and the use of inappropriate tools are example of reasons for the low reuse activity. In this sense, this work presents a semantic layer applied to a source code search tool with the objective of bringing real relevant returns closer to user need, and, consequently to increase the chance of reuse. Two new components are proposed for the execution of the semantic activities and the resulting semantic search engine is evaluated with a realistic environment configuration analogous to projects from software organizations.

Outline: The main contribution of this work refers to the semantic layer applied to a keyword-based search engine in order to increase the precision of search returns. The proposed solution utilizes a domain ontology for enhancing the construction of the query with related terms and a machine learning technique for source code classification. The implemented proposal configures a viable and practical solution for being utilized in an industrial scenario in favor of source code reuse. Through the real experiment, it was evidenced the increase of precision during the code searches and this finding goes against the semantic conceptual gap between user needs and machine understanding.
The full text you can get here.

Sunday, April 6, 2008

Proactive Bug Reports Discover


The developers behind PyGame have introduced a proactive way to capture bugs discussion that have not reported to the PyGame mailing list [yeah, they use email list to report bugs]. The motivation is the fact that users, sometimes, associate the PyGame's problems to the operational system is running, which lead them to report the problem to the OS's bug tracker, or simply discuss about PyGame's problems in personal blogs or whatever.

The method proposed in PyGame's blog is interesting and consists in searching into specific places [sites, mailing lists etc] to find bug reports related to PyGame. However, some questions about viability and scalability rise, such as: what about the cost to maintain crawlers searching for bug discussion in the web? How to decide if a bug discussion is really relevant or if it is really a bug? etc.

For PyGame's developers, this solution is reasonable because they have specifics web sites, mailing lists, and CR tracking systems, where the searches must be performed. But, for widely used softwares, such as Firefox web browser, the technique might be very costly, or even impracticable.

Thursday, February 28, 2008

More on Change Request Duplication Problem

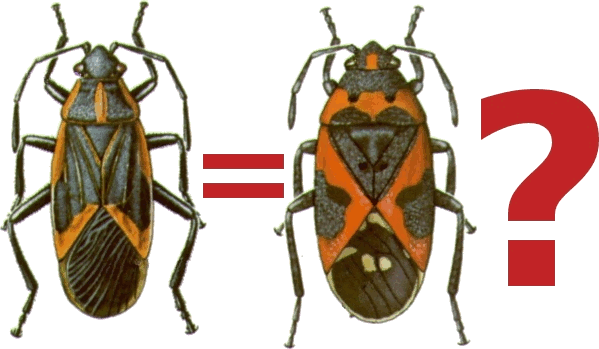
This to CR are iqual?
In a previous post we had a little discussion about Change Requests duplication problem, showing how it can impact on software development and some works that approached it. However, our curiosity led us to a much bigger investigation of the problem to see its real dimension.

Thus, with this objective in mind, was performed a formal characterization study of CR duplication problem to see how it impacts on software development productivity. Furthermore, it was selected several different projects -- which include private and open source projects -- with different characteristics in order to expand our study as much as possible. Among these characteristics, we can cite software domain, team size and experience, software size and life time, CR tracking system used, and so on. In addition, it was performed some interviews with developers and people which deal with CR tracking systems.

The values and answers obtained for the metrics and questions we have defined confirmed the initial expectations, in most cases passing them, showing that the CR duplication problem is very critical to the project productivity, evolution and maintenance. In other words, many hours are lost in the task of identifying duplicate CRs, which could be used with other tasks. In addition, not only hours are lost, but also this problem turns difficult the engagement of new people to deal with CR tasks. In the last case, it happens because people need to have a good knowledge of the past CRs of a repository in order to avoid the problem.

Moreover, we have not only performed this characterization study but, given that the problem has a industrial scale, some studies and works is being conducted to solve the problem. For example, an approach based on keyword-based search engines was applied to the problem. However, although the result were satisfactory, we think that it can be improved much more with the combination of other techniques.

Tuesday, November 20, 2007

Towards a Query Reformulation Approach for Component Retrieval

This post presents topics related in the seminar that we had today for I.N.1.0.3.8 - Advanced Seminars in Software Reuse course at Cin/UFPE. The title is "Towards a Query Reformulation Approach for Component Retrieval". The presentation (see) evaluates several papers about Query Reformulation, exploring theirs approaches and strategies.

Software construction is done more quickly when a reuse process is adopted. But this is not enough if there is no market to absorb these software components. The component market still faces a wide range of difficulties such as lack of a efficient search engine.

One of the biggest problems in component retrieval and search is to increase the significance of the result since the user normally doesn´t formulate the query of the appropriate way. The searcher has a vision of the problem that is not necessarily the components repository reality. Several approaches try to solve this problem. The seminar focuses on the query reformulation technique which reduces the conceptual gap between problem and solution through query refinement based on formulated queries stored previously.

The Code Finder was one of the first attempts to implement component search and retrieval by query reformulation. The papper "Interactive Internet search: keyword, directory and query reformulation mechanisms compared" evaluates that query refomulation improves the relevance of documents, but increase search time. The work "Using Ontologies Using Ontologies for Database Query Reformulation" do query reformulation using ontology rules for query optimization and for data integration. Another very interesting study is "Lexical analysis Lexical analysis for modeling web query reformulation" that analyzes lexicaly the searcher behavior through that Query Clarity and Part-of-Speech.

My initial proposal is to develop a query reformulation engine for BART, using techniques that will be evaluated such ontology, keywords order and other. Approaches comparison matrix will be prepared to compare the several existing techniques e helps in the correct choose.

by Dimitri Malheiros

Monday, October 29, 2007

BTT - Towards a Bug Triage Tool

Today we had a seminar for I.N.1.0.3.8 - Advanced Seminars in Software Reuse course at Cin/UFPE about current works/researches on mining software repositories, especially bug and source repositories. For one that is not familiar with challenges raised by these kinds of repositories this text can be interesting.

About the presentation, among challenges related to bug and source repositories were presented works and current researches about Impact Analysis, Automated Bug Report Assignment, Automated Bug Report Duplication Detect, Understanding and Predicting Software Evolution, Team Expertise Determination, Bug Report Time to Fix and Effort Estimation, and Social networks.

For each of these challenges were presented how researches has been addressed the problem, e.g. what techniques has been used, and the achieved results for each approach. In addition, issues about techniques and test framework for some works were mentioned. However, despite the number of challenges, the presenter focuses on Duplication Detect problem, which has few works about and is more crucial in bug triage process and tools.

Among the presented works for Duplication Detect problem, that were only 3, we can cite the paper from Runeson which attacked the problem using NLP techniques, the MSc dissertation from Hiew using a cluster based approach with cosine similarity measurement, and the paper from Anvik that presented some resulted using statistical model and text similarity.

Some consideration also were made: among revised works, only one had been tested in an industrial scale (Runeson´s paper), the others are academic prototype only; more real test cases with a greater number of different software projects and bug databases are needed; the major part of the works are project process dependent, which blocks the approach generalization for other software projects; and the efficiency of the approach vary from 20% to 40% only, that is a very low range.

Furthermore, the presenter left some open questions about a tool development in the future: would be better to develop a bug triage tool from scratch, or to develop plug-ins for most used tools or adapt some existing tool to create a new one? What technique to use - NLP, TDT, Text Mining techniques or a mix of them?

Participants of the seminar also discussed about things like how to handle meta-bugs (bugs that describe others bugs) in the approach and what is the reuse motivation for the Duplication Detect problem. For reuse motivation we can argue for quality improvement, cost reduction and time saving, that, in general, is the idea of software reuse. And for meta-bugs, that are very common in open source development, probably we must threat this at pre-processing operations of bug reports.

Download the presentation PDF here

Tuesday, September 18, 2007

The bad side of Bug Repositories

In the last eight years, approximately, bug repositories, especially in Open Source Software, has gained much more focus by researchers, increasingly considerably the literature about it. These repositories are being analyzed by information retrieval perspective for Software Engineering (see 1 and 2), in an attempt to improve and automate some processes related to them. Bug repositories are systems to collect bugs founded by users and developers during a software usage.

As some people has noticed, the majority of open source software, and proprietary software too, has been organized their development processes around a bug repository system. This means that bugs resolution, new features and even improvements in the process, are being dictated by bug reports. Here, we mean by bug a software defect, change requests, features requests, issues in general.

The task of analyzing reported bugs is called bug tracking or bug triage, where the word "bug" could, reasonably, be replaced by issue, ticket, change request, defect, problem, as many others. But the more interesting is to know that bug tracking tasks are done, in general, by developers and a precious time is taken for this. Beside many others sub-tasks in bug triage, we can cite: analyzing if a bug is valid; trying to reproduce it; dependency checking -- that is, verify if other bugs block this bug and vice-versa; verify if a similar bug has been reported -- duplication detect; assign a reported bug to a developer.

Many other sub-tasks can be identified, however, in attempt to show the problem that bug triage could be the in software final quality, we'll concentrate our efforts on bug duplication detect task, witch actually is manually made, as many others.

In a paper by Gail Murphy, entitled Coping with an open bug repository, we can see that almost 50% of reported bugs during the development and improving phase are invalid. That is, are bugs that could not be reproduced (here we include the well know "works for me" bugs), bugs that wont be resolved, duplicated bugs, bugs with low priority, and so on. And 20% of this invalid bugs are only duplicated bugs, that is, bugs that was early reported.

Putting it in numbers, lets suppose that a project receive about 120 bug reports by day (in some projects this average is much more bigger), and that a developer spent about 5 minutes to analyze one bug. Doing simple arithmetic operations, we see that 10 hours per day, or 10 persons-hour, are wasted only in this task (bug tracking), and about 5 hours are wasted only with bug that does not improve the software quality. And only for duplicated bugs we have 2 wasted hours. Now calculate it for a month, for a year! That is, the automated invalid bugs detection, in special duplicated bug detection, is a field to continue being explored; many techniques has been tested. A good technique can save these wasted hours and put them in a health task.

Another thing which we can mention is that if a software product line approach is used, the problem of duplicated bug reports can increase significantly. Since, products have a common platform, many components are reused. That is, as the same component are used in many products, the probability of reporting the same bug by different people are higher. Moreover, the right component must be correctly identified in attempt to solve the bug, if not the problem still occurring in the product line.

One could not see at a first glance, but the bug repositories analysis, specially the detection of duplicated bugs, has much to see with software reuse. Software reuse try to reduce costs, make software development process faster, increase the software quality and other benefits. Improvements in bug triage processes aims to do exactly this!

Bug repositories came as a new challenge for emergence Data Mining for Software Engineering field. Many techniques from intelligent information retrieval, data mining, machine learn and even data clustering, could be applied to solve these problems. The actually researches results has achieved only 40% (as a maximum) of effectiveness on trying to automate these tasks, witch characterize a semi-automated solution.

Post by Yguaratã C. Cavalcanti, M.Sc. candidate at CIn-UFPE and RiSE member.